Controlled CivBench on Vox Populi 5.2.7, Civilization V
PredictionA controlled version of CivBench (Chen et al., 2026). Each LLM strategists rotate through 3 standard maps (8 players), each game features 2 of the same LLM strategists + 6 Vox Populi AI players. Experimented with 2 conditions: having LLMs make a decision every turn (base); having them make a decision every 5 turns, or when an important event comes up (per-5).
Compare how well win-probability estimators predict game outcomes, since these estimates underpin the strength scores used to evaluate strategists.
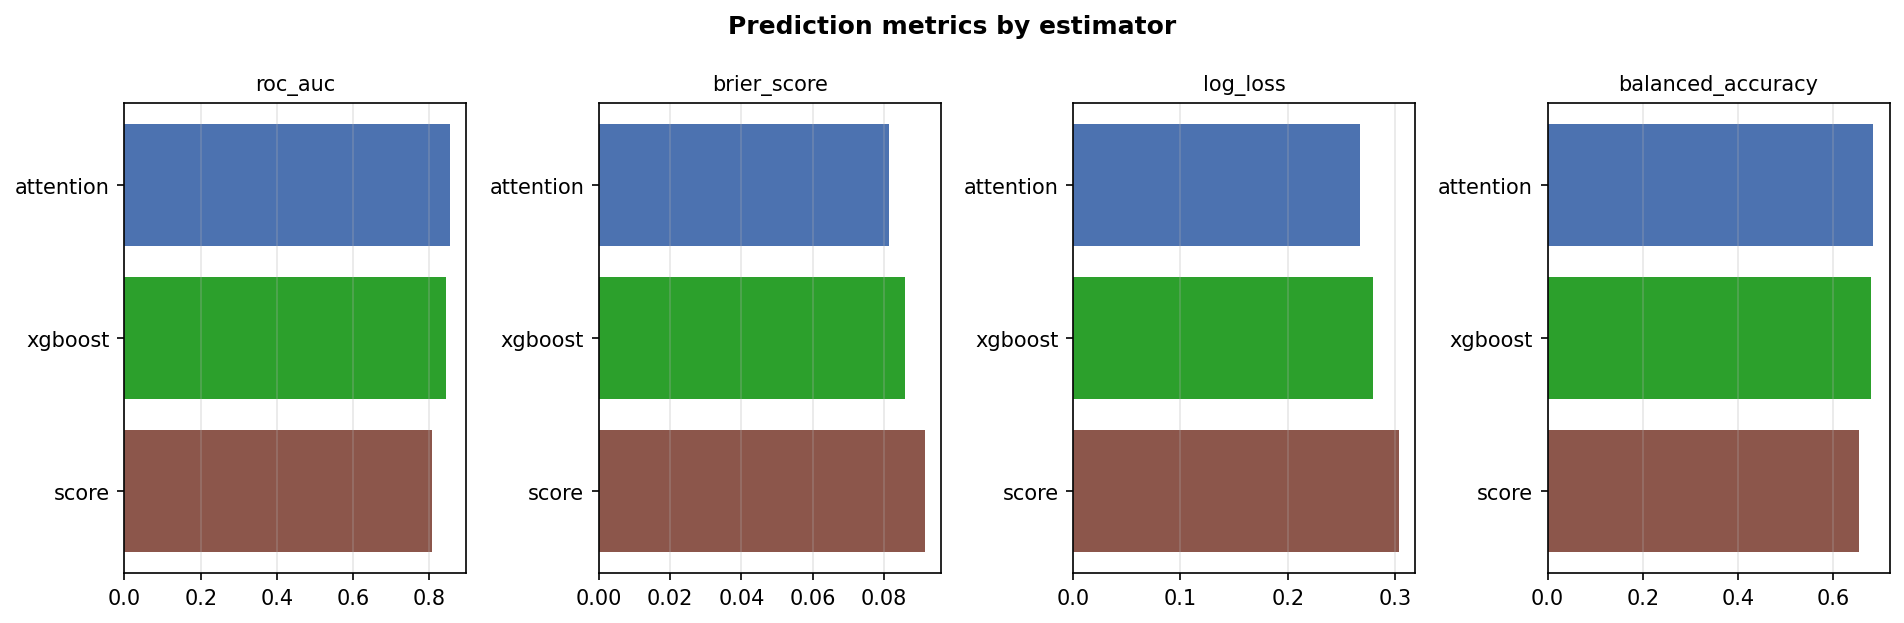
Prediction qualityMeasures how well each estimator identifies likely winners and matches observed outcomes (discrimination and calibration). Module: prediction.evaluate metrics: roc_auc, brier_score, log_loss, balanced_accuracy; n_models: 3
attention performs best on roc auc at 0.8545 using 770 games; scores range from 0.8066 to 0.8545.
metrics
| model | n_rows | n_games | roc_auc | brier_score | log_loss | balanced_accuracy |
|---|---|---|---|---|---|---|
| score | 2541288 | 770 | 0.806588 | 0.091384 | 0.303654 | 0.654266 |
| attention | 2541288 | 770 | 0.854509 | 0.0812848 | 0.267131 | 0.684316 |
| xgboost | 2541288 | 770 | 0.843815 | 0.0857789 | 0.279718 | 0.679666 |
Downloads and supporting files (1)
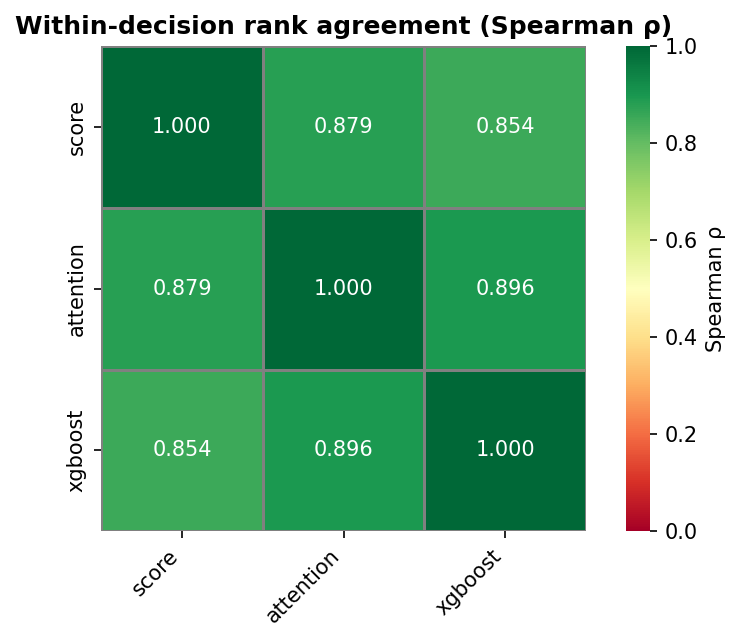
Estimator agreementShows how closely estimators agree on win probabilities and on the within-turn ranking of players. Module: prediction.compare n_models: 3; n_rows: 2541288
attention and xgboost agree most on player rank (Spearman 0.896); agreement ranges from 0.854 to 0.896 across 2,541,288 shared predictions.